Input
image_url
File 1
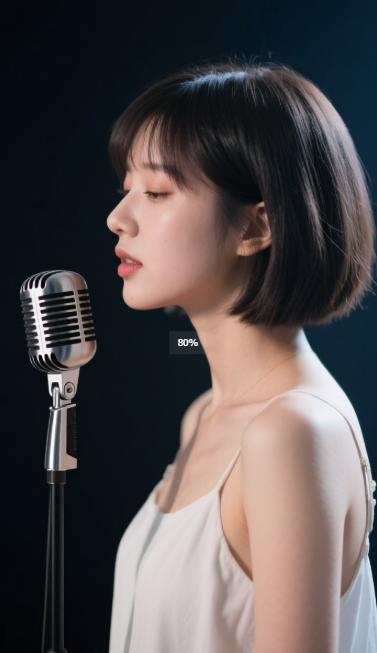
File uploads require configured image storage. A public HTTPS image URL can be used directly.
Portrait image URL, supports any aspect ratio with subjects including people/pets/anime, etc.
0
To have a specific subject in the image speak, use 'Subject Detection' to get the corresponding mask image and pass it as input.0
audio_url
File 1
File uploads require configured image storage. A public HTTPS image URL can be used directly.
Audio URL. Duration must be < 60 seconds (recommended ≤15 seconds; exceeding this will cause degradation).
Prompt text, limited to Chinese/English/Japanese/Korean/Spanish/Indonesian, recommended ≤300 characters.65/300
Output video resolution, default 1080.
Fast mode, sacrifices some quality to speed up generation.
Random seed. Default is -1 (random). When using the same positive integer and keeping all other parameters identical, the result will be highly consistent (with very high probability).
Output
More AI models from ByteDance
Latest and popular AI models
README
Complete guide to using omnihuman-1-5